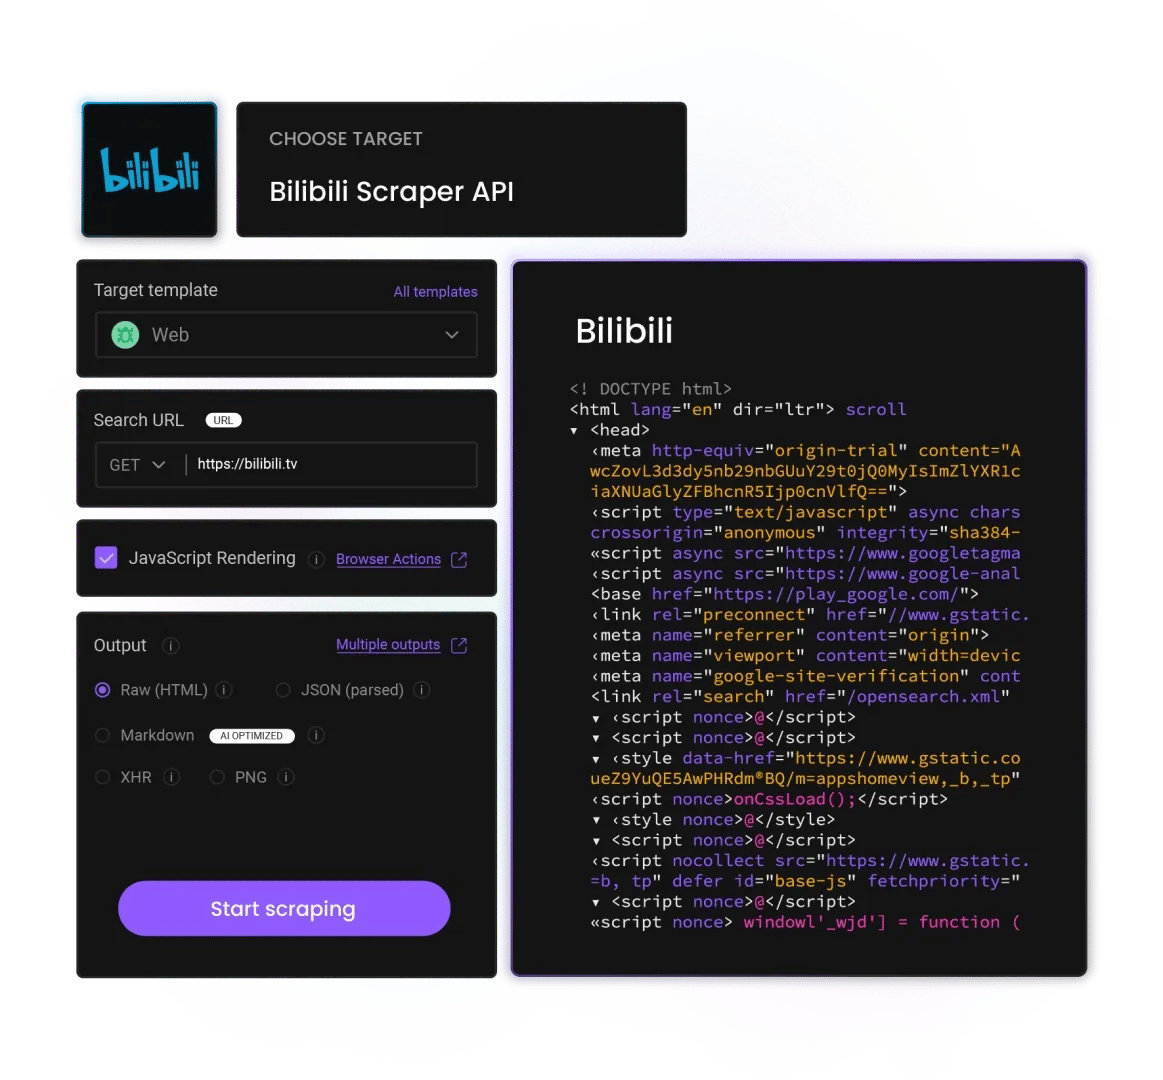
China's youth-culture video platform has no official open Bilibili API – what exists is reverse-engineered and shifts without notice. Our scraper API collects the public metadata layer instead: rankings, view counts, danmaku volumes, and uploader stats, with China-side access built in.
* This scraper is now a part of the Web Scraping API.
125M+
IPs worldwide
99.99%
success rate
200
requests per second
100+
ready-made templates
Free
starter plan

Scope defines this page: the target is Bilibili's metadata, not its media. Video files carry copyright and stay out of collection entirely – what the public pages offer is the measurement layer:
Brands running China marketing read Bilibili rankings as youth-demographic trend data, MCN agencies track creator trajectories, and researchers study the platform's distinctive engagement culture. Community Bilibili API wrappers exist but break unannounced – public pages are the surface that stays public.

Trend measurement is diff work on a schedule. The Web Scraping API samples ranking and video pages through China-appropriate origins, and count fields – views, danmaku, coins – become time series that show acceleration, which is the actual trend signal. The Social Media Scraping API brings the same engagement-metrics treatment to platforms outside the Chinese ecosystem, so cross-platform creator analytics share one pipeline shape.
Built-in scraper
JavaScript rendering
Easy API integration
195+ geo-locations, including country-, state-, and city-level targeting
No CAPTCHAs or IP blocks
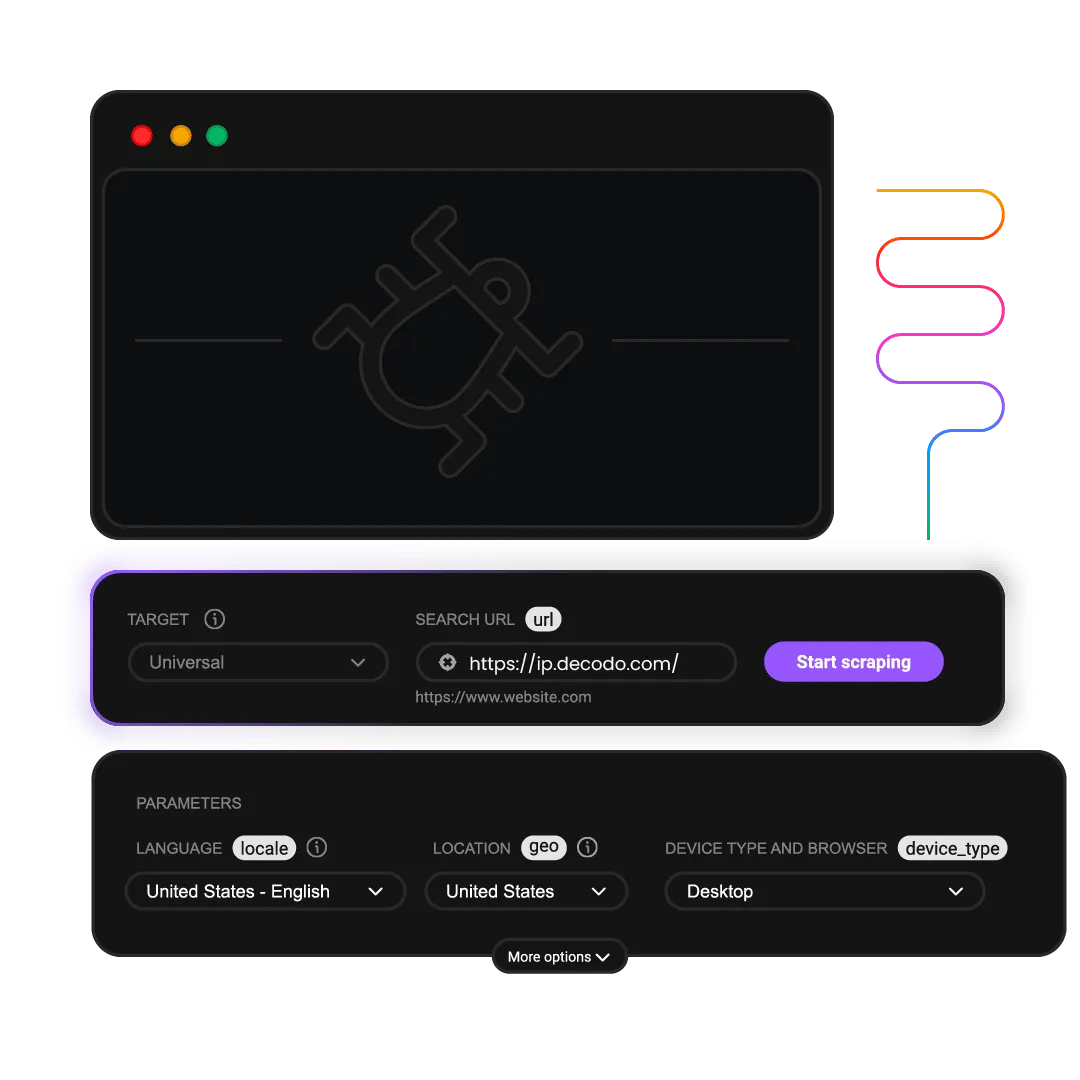
Our Bilibili Scraper API supports all popular programming languages for smooth integration with your business tools.
Scrape Bilibili using an API that handles JavaScript rendering and proxy integration for you, so you get the data you need without blocks or CAPTCHAs.
100% success rate
Metadata pages only bill when they arrive – regional friction recycles at no cost.
Advanced anti-bot bypass
Chinese platforms run their own detection styles – CN-plausible origins and steady rhythms carry collection.
Real-time or on-demand results
Check one video's velocity an hour after upload, or archive full category rankings daily.
125M+ proxy pool
CN-side exits are the working baseline – the platform serves its home audience first.
JavaScript rendering
Rankings and count widgets paint client-side – rendering delivers the numbers as shown.
Easy integration
Ranking and video URLs are stable and enumerable – category coverage is a compact target list.
Choose a plan based on your scraping volume. All plans include the same powerful features – you only pay for what you use. Start with the free plan to test before committing.
Plan prices
+VAT / Billed monthly
Rate limit
All prices shown are per 1K req.
Plan price
$0
+VAT / Billed monthly
Request type
Price per 1k req.
2K req.
$0.50
1K req.
$0.75
1K req.
$1.00
667 req.
$1.50
Rate limit
10 req/s
Plan price
$19
+VAT / Billed monthly
Request type
Price per 1k req.
38K req.
$0.50
25K req.
$0.75
19K req.
$1.00
12K req.
$1.50
Rate limit
10 req/s
Plan price
$49
+VAT / Billed monthly
Request type
Price per 1k req.
163K req.
$0.30
75K req.
$0.65
54K req.
$0.90
39K req.
$1.25
Rate limit
25 req/s
Plan price
$99
+VAT / Billed monthly
Request type
Price per 1k req.
707K req.
$0.14
165K req.
$0.60
116K req.
$0.85
82K req.
$1.20
Rate limit
50 req/s
Need more?
Request type
Price per 1k req.
Custom
Custom
Custom
Custom
Rate limit
Custom
For low-security sites and simple access
For accessing guarded or sensitive pages
With each plan, you access:
99.99% success rate
Results in HTML, JSON, CSV, XHR or PNG
MCP server
JavaScript rendering
AI integrations
100+ pre-built templates
Supports search, pagination, and filtering
LLM-ready markdown format
24/7 tech support
14-day money-back
SSL Secure Payment
Your information is protected by 256-bit SSL
135K+ developers, SEOs, and data teams rely on Decodo to collect public web data at scale – including from Bilibili. Whether you're shipping a side project or running production pipelines, our infrastructure is built to keep your Bilibili scraper running while you focus on what to do with the data.
Decodo
Manual data collection
Other APIs
125M+ residential, mobile, datacenter, and ISP proxies
Manage proxy rotation yourself
Limited proxy pools
Advanced browser fingerprinting
Build CAPTCHA solvers
Frequent CAPTCHA blocks
Only pay for successful requests
Handle retries manually
Pay for failed requests
100+ ready-made scraping templates
Maintenance overhead
Complex documentation
Data in JSON, CSV, HTML, and Markdown formats
Days to implement
Limited output formats
135K+ developers, SEOs, and data teams rely on Decodo to collect public web data at scale – including from Bilibili. Ship a side project or run production pipelines – our infrastructure keeps your Bilibili scraper running while you focus on what to do with the data.
Attentive service
The professional expertise of the Decodo solution has significantly boosted our business growth while enhancing overall efficiency and effectiveness.
N
Novabeyond
Easy to get things done
Decodo provides great service with a simple setup and friendly support team.
R
RoiDynamic
A key to our work
Decodo enables us to develop and test applications in varied environments while supporting precise data collection for research and audience profiling.
C
Cybereg
Trusted by:
Build knowledge on our solutions and improve your workflows with step-by-step guides, expert tips, and developer articles.
Most recent

IPv4 vs. IPv6: Key Differences and Which One to Use
Understanding IPv4 vs. IPv6 is essential as the internet's aging infrastructure strains and legacy IPv4 runs out of room. IPv6 steps in as the long-term solution, offering a virtually limitless address space, built-in security, and efficient routing. This article explores their key differences, core benefits, and the practical challenges of transitioning.
Justinas Tamasevicius
Last updated: Sep 25, 2026
8 min read
Faces and voices attract their own rules. Video and images collected from Bilibili can carry identifiers that text never would. Treat those files as the sensitive part of the record. Our personal data in video and images explains what applies.
Detection here follows Chinese-platform conventions – origin plausibility, session behavior, and rate rhythms. China-side exits, rendered sessions, and measured pacing form the posture, with automatic retries covering challenges. Metadata cadences sit comfortably inside sustainable rates.
Ranking and video pages arrive as HTML, or as count-field JSON typed numerically – view velocity math wants integers, not strings. The YouTube scraper API extends the identical metadata approach to the global video ecosystem.
China-side origins are the practical requirement – the platform serves complete, current data to its home market first. In-China exits anchor collection, with the rest of the 195+ geo-locations available for comparing any internationally-served surfaces.
Daily archives of every category's rankings plus hourly sampling of tracked videos is a modest scheduled workload. Concurrency follows plan tier, responses arrive in seconds through appropriate origins, and upload-spike events – festival weeks, viral moments – fit the same pipeline at denser cadence.
Yes – the free starter plan is card-free and carries up to 2K requests. A two-week trend-tracking pilot on a category fits comfortably inside that. Judge the metadata quality against your China-market questions directly.
Gain access to real-time data at any scale without worrying about proxy setup or blocks.
14-day money-back option