Data Collection
The process of data collection is vital in all kinds of industries. It helps businesses learn about the market, know their customers better and adapt to their needs. Data collection can be automated by scraping a set target. It’s extra useful for analyzing business competition, records, trends, and other data.
14-day money-back option
How to Build a Grubhub Promo Offer Scraper in Python
A Grubhub promo offer scraper collects the discounts and perks attached to restaurants. Requesting a restaurant page won't return any of them: Grubhub answers with HTTP 200 and 13,631 bytes of JavaScript shell, byte-identical to the homepage. This guide reverse-engineers the 2 Grubhub endpoints that return the data, builds a working promo collector in Python, and measures what each one omits.

Justinas Tamasevicius
Last updated: Aug 28, 2026
17 min read
Cloudflare Precursor: What It Means for Web Scraping and Browser Automation
Cloudflare Precursor is a behavioral bot-detection system that constantly analyzes how visitors interact with a website throughout a browsing session. It doesn't check your identity once at a single checkpoint (like a CAPTCHA); instead, it monitors how you interact with the site, such as your mouse movement, keyboard activity, and scrolling. So when you're web scraping or running any sort of browser automation, your script now has to behave like a human for the entire browsing session, not just at certain points like the CAPTCHA point.
Justinas Tamasevicius
Last updated: Aug 28, 2026
5 min read
Agentic Commerce: Why AI Shopping Agents Get Blocked
Agentic commerce means an AI agent does the shopping: it searches catalogs, compares prices, and sometimes checks out. Retailers are meant to expose a protocol for that. When none is published, the agent reads the product page like a person. We ran 10 US retailer pages through 4 clients, and the best one we built read 5 of them. Adding a real browser didn't help. Correcting its client hints did.

Mykolas Juodis
Last updated: Aug 26, 2026
16 min read
HTTPX vs. Requests vs. AIOHTTP: How to Choose the Right Python HTTP Client
HTTPX, Requests, and AIOHTTP all make HTTP requests, but they differ in how they handle concurrency. Requests is synchronous, HTTPX supports sync and async with HTTP/2, and AIOHTTP is async-only and optimized for high concurrency. This article compares their architecture, performance, proxy setup, migration paths, and common production scraping pitfalls.
Justinas Tamasevicius
Last updated: Aug 26, 2026
12 min read
How to Use Wget With a Proxy: Setup, Auth & SOCKS5 (2026)
Wget is a command-line downloader, and a Wget proxy routes its requests through a different IP address so bans and geo-restrictions don't stop your job. It natively supports routing traffic through any HTTP, HTTPS, or FTP proxy server to fetch files securely. This guide covers three ways to configure a Wget proxy, authenticating and rotating it at scale, working around Wget's missing SOCKS5 support, and troubleshooting the errors you'll hit along the way.

Lukas Mikelionis
Last updated: Aug 24, 2026
15 min read
Kimi Code CLI Guide: Setup, MCP, and Kimi CLI Differences
You run kimi mcp add to connect to an MCP server. Kimi Code CLI returns the unknown command 'mcp'. Nothing is broken: Moonshot AI publishes 2 builds that both install a command named kimi, and the mcp subcommand belongs to the other build, where it's documented and works. This guide covers which build to install, how to connect MCP servers, what model access costs, and where the built-in fetch tool stops working on pages with bot detection.
Justinas Tamasevicius
Last updated: Aug 21, 2026
12 min read
How to Use cURL in JavaScript: Fetch, Axios, and Best Practices
Running cURL in JavaScript means translating a terminal cURL command into a JavaScript or Node.js HTTP request using native APIs or external libraries. If you need to migrate a working terminal cURL command into your codebase, you have options. You can execute the system cURL binary directly using child_process or node-libcurl, or rewrite it natively using Fetch or Axios. This guide provides a flag-by-flag cURL-to-JS translation guide and a decision framework to help you choose the best approach for your stack.

Zilvinas Tamulis
Last updated: Aug 20, 2026
20 min read
Best Proxies for Ad Verification in 2026
Ad verification is the process of checking that an ad was actually served, where it was reported, to real people, in the intended location. The process depends on a non-advertiser vantage point to provide unbiased metrics. Proxies are the strongest infrastructure layer for independent ad verification. By routing requests through real local IP addresses, auditors can view ads as consumers. This article compares the best proxies for ad verification: Decodo, Bright Data, Oxylabs, SOAX, and IPRoyal.
Mykolas Juodis
Last updated: Aug 19, 2026
7 min read
LLM Honeypotting: What It Is and How to Scrape Around It
LLM honeypotting is an emerging deception tactic where websites feed AI crawlers and scrapers plausible-looking but fake or worthless content. That fake data discourages scraping by raising compute costs and degrading what gets collected. It isn't widespread yet, but it's gaining traction. This guide covers what it means for you if you run a scraper, and how to keep your data pipeline clean.
Justinas Tamasevicius
Last updated: Aug 18, 2026
9 min read
DeepSeek Harness Web Scraping: MCP, Skills, and CLI
DeepSeek Harness (dsh) is an open-source agent runtime released in August 2026 under the MIT license, where models, tools, and skills all load as plugins. The plugin model means external data sources mount cleanly, but the built-in fetch and search tools still return blocked pages, empty JavaScript shells, and geo-wrong results on real sites. No commercial scraping provider has shipped a dsh integration yet, so this walkthrough uses tested config instead. You'll leave with three tested ways to give a dsh agent structured data from live sites.
Zilvinas Tamulis
Last updated: Aug 07, 2026
21 min read
Akamai Bypass: How to Get Past Akamai Bot Detection in 2026
Akamai is one of the most widely deployed bot management systems on the web, and one of the hardest to scrape around. It sits between visitors and a site's servers, analyzing every request across multiple layers to decide what's a real user and what's automated. This guide breaks down how that detection works, the practical techniques for getting past it, and where the technical and legal limits sit.
Zilvinas Tamulis
Last updated: Aug 07, 2026
20 min read
Wikimon Scraper: Build a Digimon Data Scraper in Python
Wikimon.net is a community-maintained Digimon wiki, but it doesn't offer a public API, so web scraping is the most practical way to pull structured data from its Visual List. In this guide, you’ll build a working Python scraper with Requests and Beautiful Soup to extract Digimon names and image URLs, then save the results to either a CSV file or a MySQL database for later use.
Lukas Mikelionis
Last updated: Aug 06, 2026
15 min read
Mobile Proxy vs. Residential Proxy: How to Choose
You can’t get any more "real" than mobile and residential proxies. Both are sourced from genuine user devices, with mobile drawing from phones on carrier networks and residential from homes with broadband. In this blog post, we’ll tackle the difference between the two, explaining how each proxy type affects trust, speed, and cost, and how to decide which one belongs in your projects.

Robertas Lisickis
Last updated: Aug 06, 2026
8 min read
How to Scrape Hidden APIs (With a Worked Example)
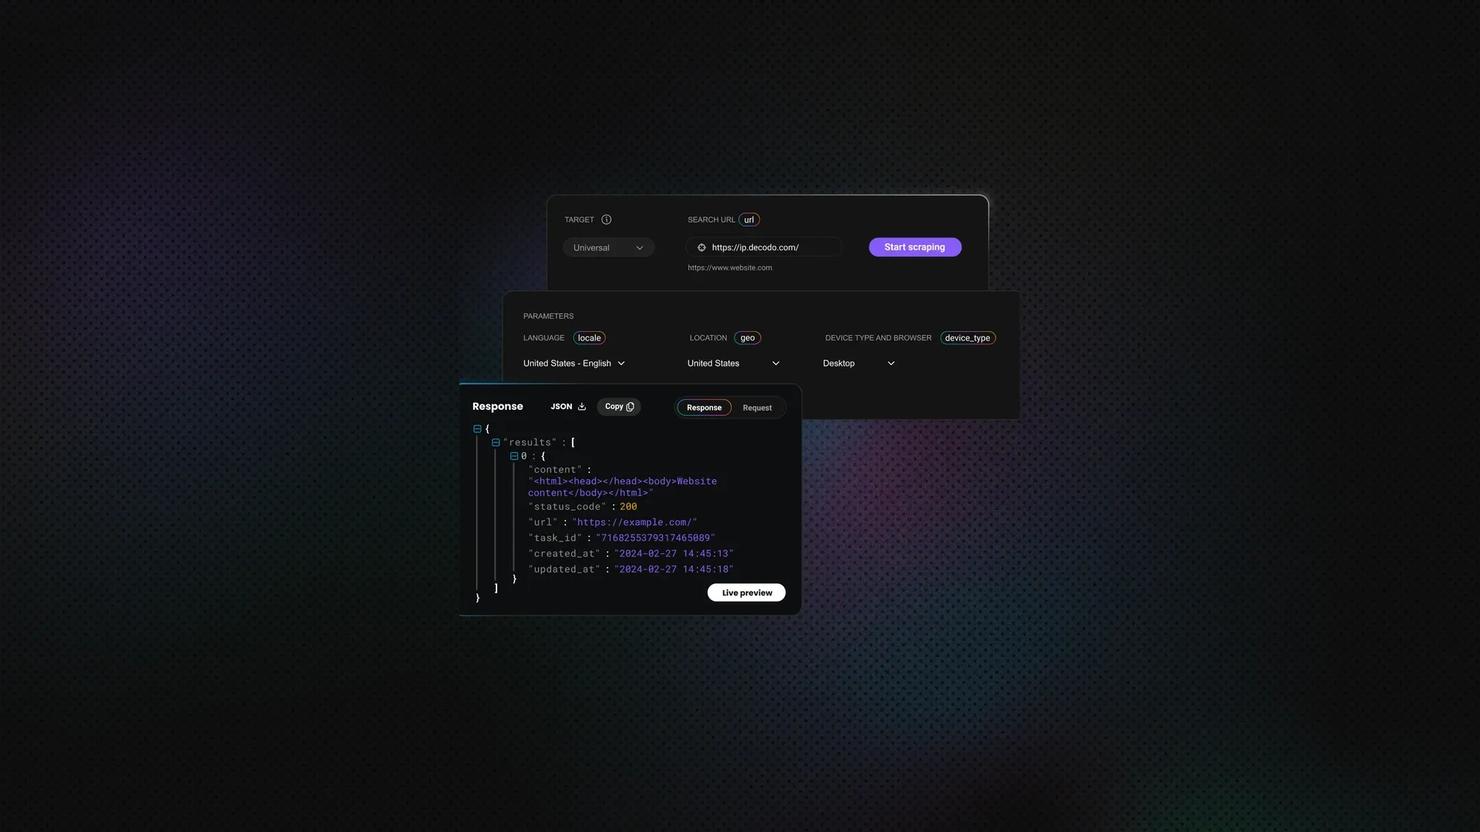
A hidden API is an undocumented endpoint that a website's frontend calls in the background, usually through XHR, Fetch, or GraphQL, to load data as JSON. Scraping hidden APIs means calling that endpoint directly instead of parsing the rendered HTML. Many modern websites load the page first, then fetch the actual data this way, so the clean JSON you need is often just one request away. In this guide, you'll learn how to find these hidden APIs and use them to collect structured data faster, without a headless browser.
Justinas Tamasevicius
Last updated: Aug 06, 2026
20 min read
How to Bypass PerimeterX: Detection Methods, Tools, and Practical Workarounds
PerimeterX, now HUMAN, is a cybersecurity platform that employs multiple detection techniques to accurately identify and block threats to web applications. Since numerous high-traffic websites rely on PerimeterX, it's almost inevitable that developers will encounter it when web scraping. This guide explains how PerimeterX detects bots, how to bypass it (tools and strategies), and how to troubleshoot common failures.
Justinas Tamasevicius
Last updated: Aug 05, 2026
12 min read
How To Scrape Christie's Auction Data: A Complete Guide
Christie's has published more than 4 million sold-lot results online since the mid-1990s, and none of them come with a public API. A Christie's scraper pulls that lot data from christies.com into a structured format like JSON or CSV, using the endpoint that the site's own search calls. This guide shows you how to build it, then covers the buyer's premium, the 10,000-result cap, and the proxy costs.
Justinas Tamasevicius
Last updated: Aug 03, 2026
17 min read
RAG Data Sources: Types, How to Build Them, and How to Keep Them Clean
Retrieval-augmented generation (RAG) lets a language model answer questions using external data rather than frozen training data alone. The sources you feed it decide how accurate, fresh, and relevant those answers are. This guide covers what RAG is, how it works, the available data source types, comparisons with related methods, and the pitfalls to plan for.

Vilius Sakutis
Last updated: Jul 31, 2026
6 min read
Imperva Bypass: How to Get Past Incapsula Bot Protection in 2026
Imperva (formerly Incapsula) protects many high-traffic retail, real estate, travel, and job listing websites, making it one of the most common obstacles you'll encounter while web scraping. But once you understand how it works, it becomes much easier to work around. In this guide, you'll learn how Imperva detects bots, practical ways to reduce blocks, and where DIY approaches start reaching their limits.

Dominykas Niaura
Last updated: Jul 31, 2026
8 min read