CNN Scraper API
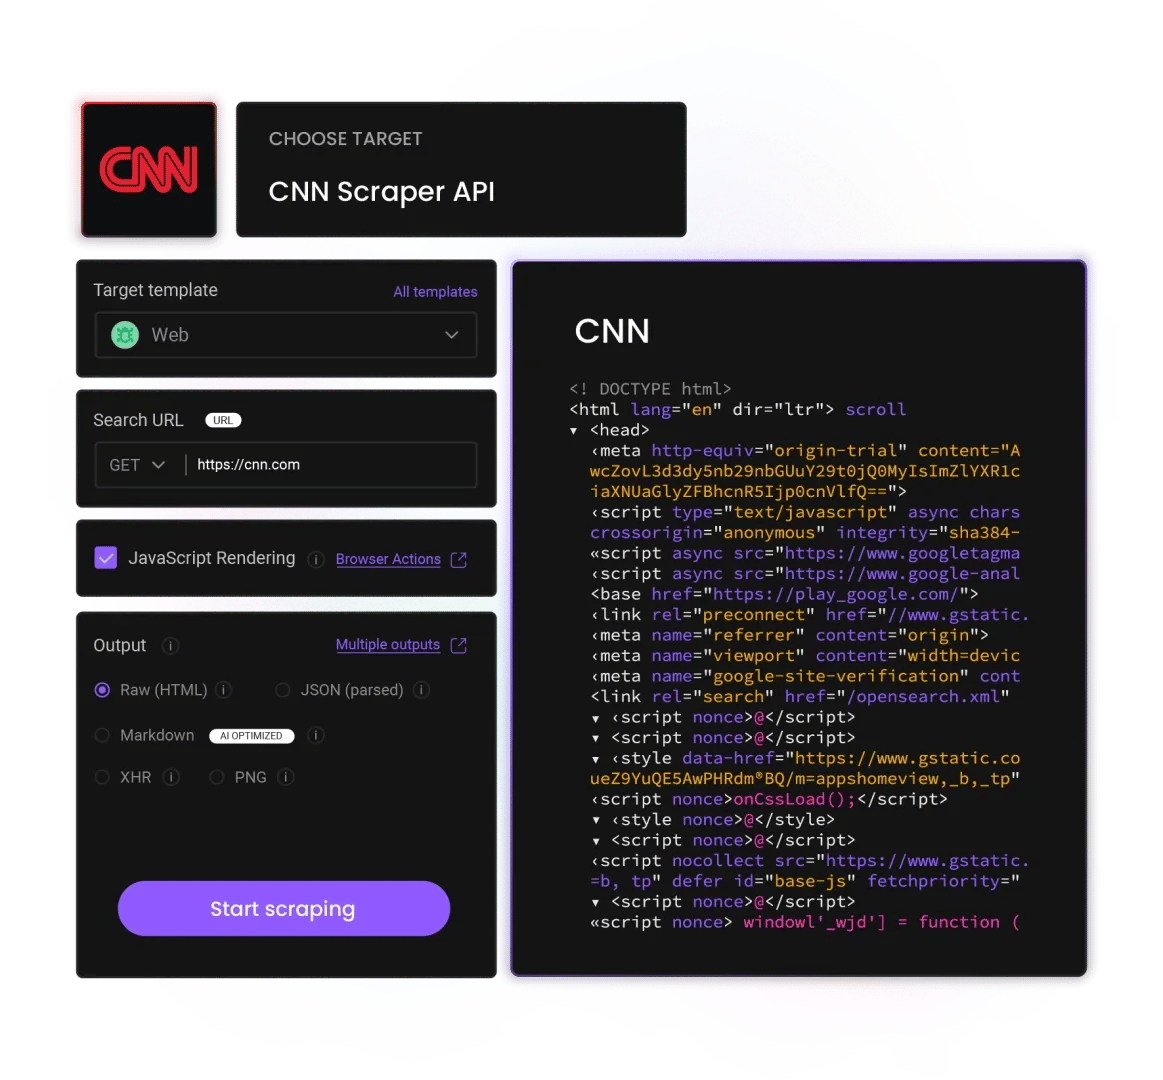
Newsrooms and monitoring desks keep hunting for a CNN API, and none is on offer. Our scraper API watches CNN's public section and article pages – headlines, timestamps, bylines, section placement – turning one of the world's fastest news operations into a structured feed for media monitoring.
* This scraper is now a part of the Web Scraping API.
125M+
IPs worldwide
99.99%
success rate
200
requests per second
100+
ready-made templates
Free
starter plan
Be ahead of the CNN scraping game
What is CNN scraper API?
A copyright boundary shapes this page before anything else: CNN's articles are the publisher's protected work, and the defensible use is monitoring, not republication. Within that line, and with no CNN API to lean on, the scraper collects:
- Headlines, decks, and publication timestamps
- Section placement and homepage positioning
- Bylines and topic tags
- Breaking-news banner appearances
Media monitors track when a story breaks and how it moves through sections, comms teams watch brand mentions in headlines, and researchers study coverage patterns. All of that runs on metadata and timing – the layer that's factual, not the prose that's protected.
Collect CNN data
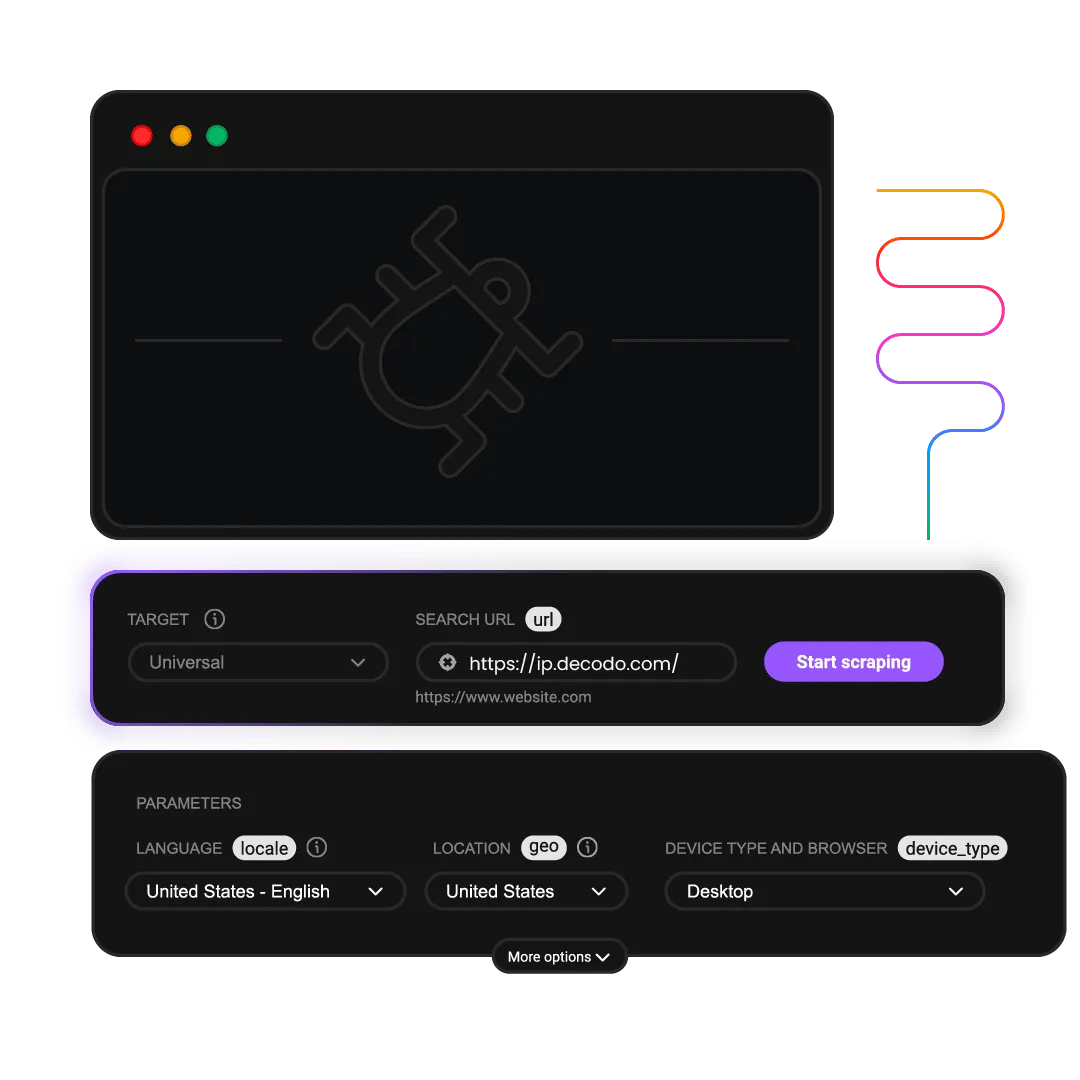
News monitoring is a latency race – the value of knowing CNN moved a story to the homepage decays in minutes. The Web Scraping API samples section pages at tight intervals, diffs surface placement changes the moment they happen, and the edition split (edition.cnn.com versus the US site) doubles as an editorial signal worth collecting on its own. For the aggregation layer across outlets, the Google News scraper API extends the same monitoring stack cross-publisher.

Built-in scraper
JavaScript rendering
Easy API integration
195+ geo-locations, including country-, state-, and city-level targeting
No CAPTCHAs or IP blocks
Scrape CNN with Python, Node.js, or cURL
Our CNN Scraper API supports all popular programming languages for smooth integration with your business tools.
Get more from the CNN scraper API
Scrape CNN using an API that handles JavaScript rendering and proxy integration for you, so you get the data you need without blocks or CAPTCHAs.

100% success rate
Section and article pages bill only when they deliver – challenges don't count against monitoring budgets.

Advanced anti-bot bypass
A major publisher's standard defenses – rate limits and IP scoring – are handled with rotation and retries.

Real-time or on-demand results
Catch a breaking-news banner within a minute, or archive section fronts on a fixed cadence.

125M+ proxy pool
CNN runs distinct US and international editions – collecting both origins reveals the editorial split.

JavaScript rendering
Homepage modules and live-update blocks hydrate client-side – rendering captures the placed state.

Easy integration
Section URLs are stable and shallow – a full monitoring target list fits on one screen.
What does Web Data API cost?
Choose a plan based on your data collection volume. All plans include the same powerful features – you only pay for what you use. Start with the free plan to test before committing.
See full pricing details in the documentation.
With each plan, you access:

JavaScript rendering
99.99% success rate
HTML, Markdown, XHR, plus JSON, CSV, PNG where supported
One-click AI integrations
LLM-ready Markdown format
100+ pre-built templates
Single API key for all endpoints
/scrape, /search, /map, /crawl
24/7 tech support
14-day money-back
SSL Secure Payment
Your information is protected by 256-bit SSL

Why the scraping community chooses Decodo
135K+ developers, SEOs, and data teams rely on Decodo to collect public web data at scale – including from CNN. Whether you're shipping a side project or running production pipelines, our infrastructure is built to keep your CNN scraper running while you focus on what to do with the data.
Decodo
Manual data collection
Other APIs
125M+ residential, mobile, datacenter, and ISP proxies
Manage proxy rotation yourself
Limited proxy pools
Advanced browser fingerprinting
Build CAPTCHA solvers
Frequent CAPTCHA blocks
Only pay for successful requests
Handle retries manually
Pay for failed requests
100+ ready-made scraping templates
Maintenance overhead
Complex documentation
Data in JSON, CSV, HTML, and Markdown formats
Days to implement
Limited output formats
Why the scraping community chooses Decodo
135K+ developers, SEOs, and data teams rely on Decodo to collect public web data at scale – including from CNN. Ship a side project or run production pipelines – our infrastructure keeps your CNN scraper running while you focus on what to do with the data.
Attentive service
The professional expertise of the Decodo solution has significantly boosted our business growth while enhancing overall efficiency and effectiveness.
N
Novabeyond
Easy to get things done
Decodo provides great service with a simple setup and friendly support team.
R
RoiDynamic
A key to our work
Decodo enables us to develop and test applications in varied environments while supporting precise data collection for research and audience profiling.
C
Cybereg

Trusted by:


Decodo blog
Build knowledge on our solutions and improve your workflows with step-by-step guides, expert tips, and developer articles.
Most recent
JavaScript Web Scraping Tutorial (2026)
Ever wished you could make the web work for you? JavaScript web scraping allows you to gather valuable information from websites in an automated way, unlocking insights that would be difficult to collect manually. In this guide, you'll learn the key tools, techniques, and best practices to scrape data efficiently, whether you're a beginner or a developer looking to streamline data collection.

Zilvinas Tamulis
Last updated: Oct 12, 2026
13 min read
Most popular
Residential vs. Datacenter Proxies: Which Should You Choose?
Residential and datacenter proxies both act as intermediaries that hide your real IP address, allowing you to access restricted websites and geo-blocked content. However, they differ in IP origin, stability, speed, and how websites perceive them. This residential vs. datacenter proxies guide breaks down their key differences.
Vilius Sakutis
Last updated: Sep 11, 2026
8 min read
Google Sheets Web Scraping: An Ultimate Guide for 2026
Google Sheets is a powerful data management tool, but few people know it can also pull data directly from the web without a single line of code. Using built-in import functions, you can scrape website content, parse tables, and pull live feeds straight into your spreadsheet. In this guide, you'll learn how to use IMPORTXML for XPath-based data extraction, IMPORTHTML for grabbing tables and lists, IMPORTFEED for RSS and Atom content, IMPORTDATA for CSV files, and IMPORTRANGE to link scraped data across spreadsheets. We'll also cover Google Apps Script for automation, common errors and how to fix them, and when to reach for a dedicated scraping tool instead.
Zilvinas Tamulis
Last updated: Mar 30, 2026
6 min read
Manage Your Business Reputation with SERP Scraping API
A widely available internet leaves the door open for people to find information about everything. For example, everyone can check a business's online presence before trusting it. So, everything that could be found online about your brand helps your potential audience evaluate if you’re legit.
Statistics only prove that – 9 out of 10 online shoppers admit that reviews influence their buying decisions. It stands to reason – checking unbiased opinions helps avoid low-value products and potential scams. And who wants that? So, for businesses analyzing their customers’ reviews becomes a not-to-miss-out factor.
However, reviews are just one part of the game. Brand reputation management consists of various elements that form the customers' perception of the company. If it’s still a gray area for you, this blog post could be your starting point.
Ella Moore
Last updated: Jun 20, 2022
7 min read
How to Scrape Google Without Getting Blocked
Nowadays, web scraping is essential for any business interested in gaining a competitive edge. It allows quick and efficient data extraction from a variety of sources and acts as an integral step toward advanced business and marketing strategies.
If done responsibly, web scraping rarely leads to any issues. But if you don’t follow data scraping best practices, you become more likely to get blocked. Thus, we’re here to share with you practical ways to avoid blocks while scraping Google.
James Keenan
Last updated: Feb 20, 2023
8 min read
What Is SERP Analysis And How To Do It?
SERP (Search Engine Results Page) analysis involves examining search engine results for specific keywords to understand website rankings. It helps identify the content, format, and optimization strategies used by top-ranking pages and uncovers opportunities for improving rankings. In this blog post, we’re exploring what SERP analysis is, how to conduct it, and how it can help you.
James Keenan
Last updated: Feb 20, 2023
7 min read
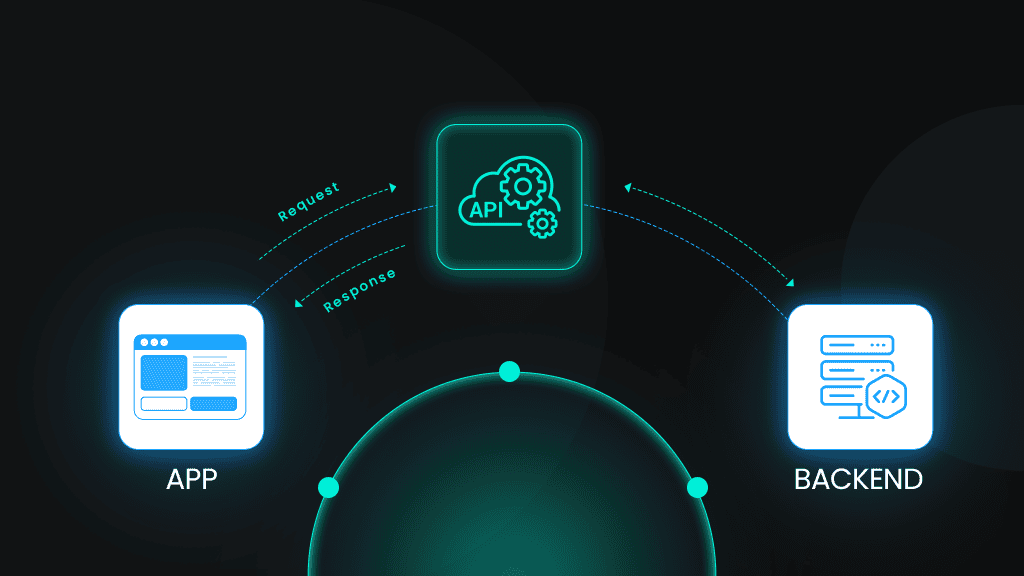
What is an API?
An application programming interface (API) works like a messenger. It allows different software systems to communicate without developers having to build custom links for every connection. For instance, one service might supply map data to a mobile app, while another handles payment processing for online transactions. In these times, that demands seamless integration, and APIs play a vital role. They automate tasks, enable large-scale data collection, and support sophisticated functions like web scraping and proxy management. By bridging diverse platforms and streamlining data exchange, they help businesses stay competitive and reduce the complexity of managing multiple, often inconsistent endpoints.
Kotryna Ragaišytė
Last updated: Mar 06, 2025
6 min read
How to Scrape Hotel Listings: Unlocking the Secrets
Scraping hotel listings is a powerful tool for gathering comprehensive data on accommodations, prices, and availability from various online sources. Whether you're looking to compare rates, analyze market trends, or create a personalized travel plan, scraping allows you to efficiently compile the information you need. In this article, we'll explain how to scrape hotel listings, ensuring you can leverage this data to its fullest potential.
Vilius Sakutis
Last updated: Nov 13, 2025
5 min read
What is Data Scraping? Definition and Best Techniques (2026)
The data scraping tools market is growing significantly, valued at approximately $875.46M in 2026. The market is projected to grow more due to the increasing demand for real-time data collection across various industries.
Vytautas Savickas
Last updated: Jan 30, 2026
6 min read
Web Crawling vs Web Scraping: What’s the Difference?
When it comes to gathering online data, two terms often create confusion: web crawling and web scraping. Although both involve extracting information from websites, they serve different purposes and employ distinct methods. In this article, we’ll break down these concepts, show you how they work, and help you decide which one suits your data extraction needs.
Justinas Tamasevicius
Last updated: Jul 01, 2025
7 min read
What Is Web Scraping? A Complete Guide to Its Uses and Best Practices
Web scraping is a powerful tool driving innovation across industries, and its full potential continues to unfold with each day. In this guide, we'll cover the fundamentals of web scraping – from basic concepts and techniques to practical applications and challenges. We’ll share best practices and explore emerging trends to help you stay ahead in this dynamic field.
Dominykas Niaura
Last updated: Jan 29, 2025
10 min read
Beautiful Soup Web Scraping: How to Parse Scraped HTML with Python
Web scraping with Python is a powerful technique for extracting valuable data from the web, enabling automation, analysis, and integration across various domains. Using libraries like Beautiful Soup and Requests, developers can efficiently parse HTML and XML documents, transforming unstructured web data into structured formats for further use. This guide explores essential tools and techniques to navigate the vast web and extract meaningful insights effortlessly.
Zilvinas Tamulis
Last updated: Mar 25, 2025
14 min read
Frequently asked questions
Is it legal to scrape CNN?
How much you keep of a protected work matters. A short reference to a CNN article and a stored copy of it are different things. Keep the smallest amount that answers your question. Our copyright limits on collected text explains the difference.
How does the CNN scraper API bypass blocks and CAPTCHAs?
CNN applies mainstream publisher defenses – IP reputation scoring, rate limiting, and JavaScript checks around live modules. Rotating exits across datacenter, ISP, residential, and mobile types with matched fingerprints keep high-frequency section sampling steady, and automatic retries cover the rare challenge.
What output formats does the CNN scraper API support?
Section and article pages stream in as HTML, or as parsed headline records – timestamp and byline isolated, what a monitoring diff wants.
Can I geo-target CNN requests to a specific country or city?
Yes – and CNN uniquely rewards it, since the international edition and US site run different front pages. Exits from 195+ geo-locations let you collect both editions plus any geo-targeted variations, turning the editorial split itself into a dataset.
How fast is the CNN scraper API and can it handle large-scale jobs?
Minute-level sampling of a dozen section fronts is a light, fast workload – these pages are built to serve under load. Concurrency scales for election-night-style bursts, and scheduling holds tight intervals reliably, which is the property monitoring actually depends on.
Can I try the CNN scraper API for free?
Monitoring pilots start free – the starter plan comes card-free and includes up to 2K requests. At a 5-minute cadence on two sections, that's several days of live monitoring to evaluate.
CNN Scraper API for Your Data Needs
Gain access to real-time data at any scale without worrying about proxy setup or blocks.
14-day money-back option