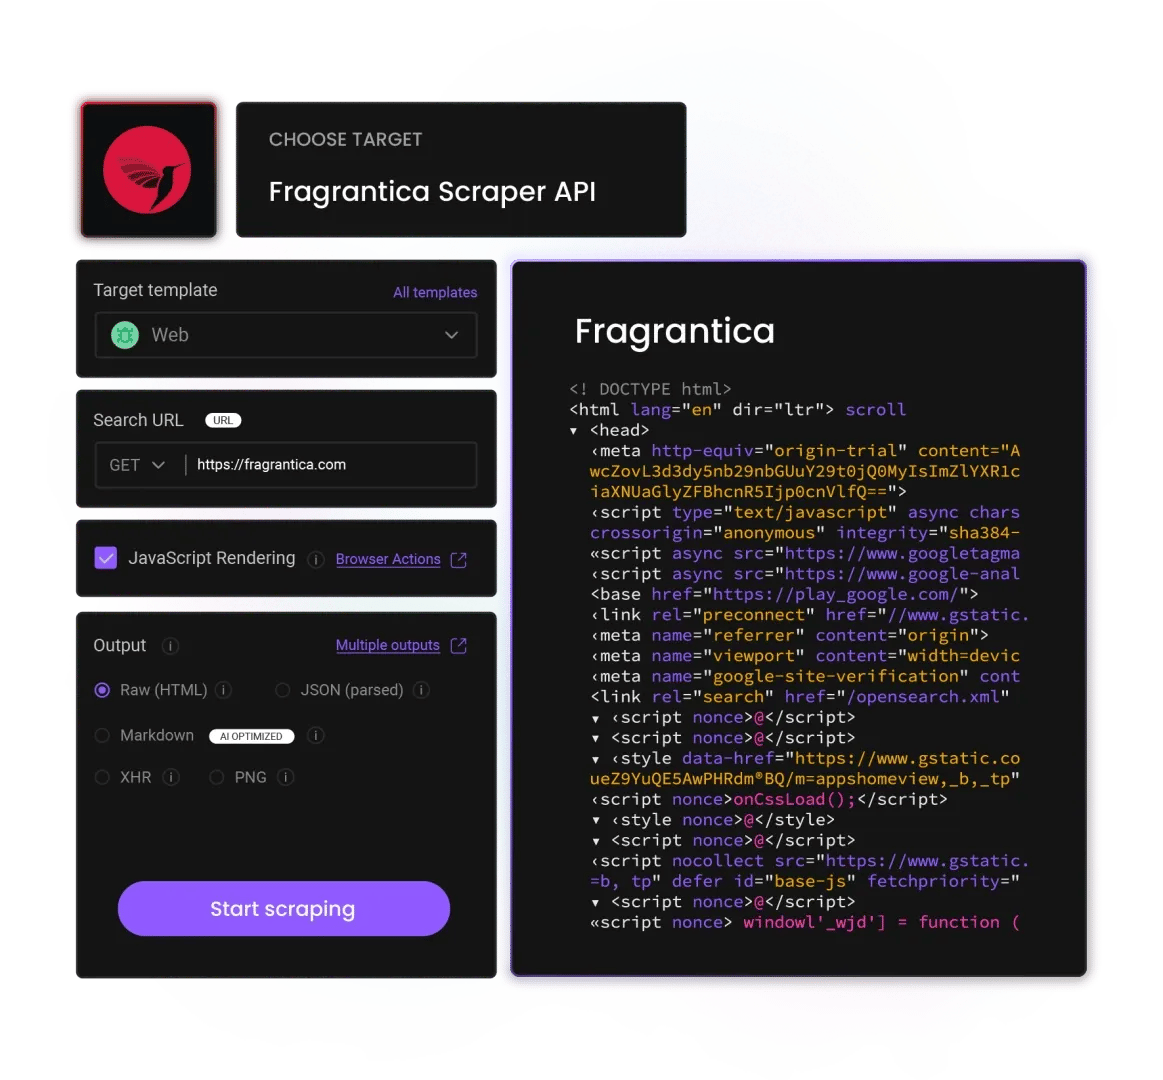
Perfume data lives on Fragrantica, and no Fragrantica API opens it up. Our scraper API reads the site's public perfume, designer, and note pages, returning the structured taxonomy – notes, accords, ratings, longevity votes – that recommendation engines and fragrance retailers build on.
* This scraper is now a part of the Web Scraping API.
125M+
IPs worldwide
99.99%
success rate
200
requests per second
100+
ready-made templates
Free
starter plan

Fragrantica scraper API extracts the fields that make the site the fragrance world's reference database:
That taxonomy is the valuable part. Perfume-matching quizzes, dupe finders, and niche retailers all run on note-level data, and Fragrantica is where it's already organized. Since no official Fragrantica API exists, the public pages are the source of record.
Fragrance data is a one-time-backfill, slow-drip-update workload – perfumes don't change their note pyramids weekly. The Web Scraping API collects designer and perfume pages through the site's commercial bot detection, and the AI Parser is a natural second stage here: note pyramids and accord bars vary in markup across page generations, and prompt-based extraction rides over those inconsistencies without selector maintenance.
Built-in scraper
JavaScript rendering
Easy API integration
195+ geo-locations, including country-, state-, and city-level targeting
No CAPTCHAs or IP blocks
Our Fragrantica Scraper API supports all popular programming languages for smooth integration with your business tools.
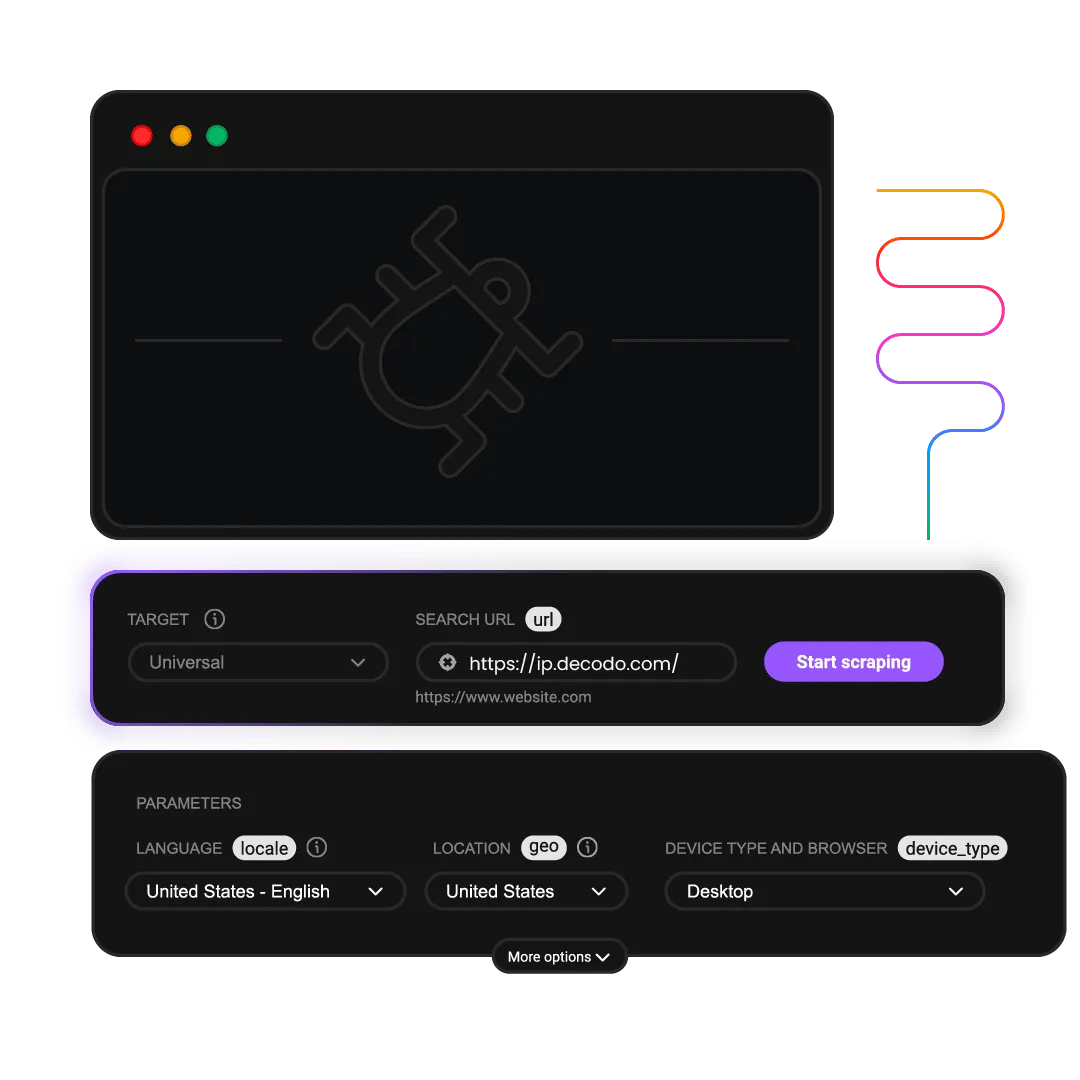
Scrape Fragrantica using an API that handles JavaScript rendering and proxy integration for you, so you get the data you need without blocks or CAPTCHAs.
100% success rate
Perfume pages bill on delivery – challenge pages and misses stay off the invoice.
Advanced anti-bot bypass
The site sits behind commercial bot detection – rotation and coherent fingerprints move through it quietly.
Real-time or on-demand results
Look up one fragrance's accords during a sourcing call, or backfill a designer's full catalog overnight.
125M+ proxy pool
Fragrance pages read the same worldwide – geo-targeting stays available but mostly rests here.
JavaScript rendering
Rating widgets and vote bars fill in client-side – rendering waits for the counts to land.
Easy integration
Designer URLs enumerate the catalog naturally – one seed page yields the full perfume list.
Choose a plan based on your scraping volume. All plans include the same powerful features – you only pay for what you use. Start with the free plan to test before committing.
Plan prices
+VAT / Billed monthly
Rate limit
All prices shown are per 1K req.
Plan price
$0
+VAT / Billed monthly
Request type
Price per 1k req.
2K req.
$0.50
1K req.
$0.75
1K req.
$1.00
667 req.
$1.50
Rate limit
10 req/s
Plan price
$19
+VAT / Billed monthly
Request type
Price per 1k req.
38K req.
$0.50
25K req.
$0.75
19K req.
$1.00
12K req.
$1.50
Rate limit
10 req/s
Plan price
$49
+VAT / Billed monthly
Request type
Price per 1k req.
163K req.
$0.30
75K req.
$0.65
54K req.
$0.90
39K req.
$1.25
Rate limit
25 req/s
Plan price
$99
+VAT / Billed monthly
Request type
Price per 1k req.
707K req.
$0.14
165K req.
$0.60
116K req.
$0.85
82K req.
$1.20
Rate limit
50 req/s
Need more?
Request type
Price per 1k req.
Custom
Custom
Custom
Custom
Rate limit
Custom
For low-security sites and simple access
For accessing guarded or sensitive pages
With each plan, you access:
99.99% success rate
Results in HTML, JSON, CSV, XHR or PNG
MCP server
JavaScript rendering
AI integrations
100+ pre-built templates
Supports search, pagination, and filtering
LLM-ready markdown format
24/7 tech support
14-day money-back
SSL Secure Payment
Your information is protected by 256-bit SSL
135K+ developers, SEOs, and data teams rely on Decodo to collect public web data at scale – including from Fragrantica. Whether you're shipping a side project or running production pipelines, our infrastructure is built to keep your Fragrantica scraper running while you focus on what to do with the data.
Decodo
Manual data collection
Other APIs
125M+ residential, mobile, datacenter, and ISP proxies
Manage proxy rotation yourself
Limited proxy pools
Advanced browser fingerprinting
Build CAPTCHA solvers
Frequent CAPTCHA blocks
Only pay for successful requests
Handle retries manually
Pay for failed requests
100+ ready-made scraping templates
Maintenance overhead
Complex documentation
Data in JSON, CSV, HTML, and Markdown formats
Days to implement
Limited output formats
135K+ developers, SEOs, and data teams rely on Decodo to collect public web data at scale – including from Fragrantica. Ship a side project or run production pipelines – our infrastructure keeps your Fragrantica scraper running while you focus on what to do with the data.
Attentive service
The professional expertise of the Decodo solution has significantly boosted our business growth while enhancing overall efficiency and effectiveness.
N
Novabeyond
Easy to get things done
Decodo provides great service with a simple setup and friendly support team.
R
RoiDynamic
A key to our work
Decodo enables us to develop and test applications in varied environments while supporting precise data collection for research and audience profiling.
C
Cybereg
Trusted by:
Build knowledge on our solutions and improve your workflows with step-by-step guides, expert tips, and developer articles.
Most recent

IPv4 vs. IPv6: Key Differences and Which One to Use
Understanding IPv4 vs. IPv6 is essential as the internet's aging infrastructure strains and legacy IPv4 runs out of room. IPv6 steps in as the long-term solution, offering a virtually limitless address space, built-in security, and efficient routing. This article explores their key differences, core benefits, and the practical challenges of transitioning.
Justinas Tamasevicius
Last updated: Sep 25, 2026
8 min read
Someone may already sell what you plan to collect. A licensed dataset covering the same ground as Fragrantica can cost less than the legal review a scraper needs. Price both routes before choosing. Our sourcing data lawfully helps with the comparison.
Expect commercial bot detection at the site's front door – challenge pages, IP scoring, and JavaScript verification. Requests arrive with rotating exits across residential, datacenter, ISP, and mobile types, browser-grade fingerprints, and automatic retries, so the occasional challenge resolves without your pipeline noticing.
Perfume and designer pages export to HTML, or to parsed JSON with note and rating fields lifted out. Markdown packages review text for sentiment models cleanly – the same pattern the review data collection toolkit applies across UGC-heavy targets.
You can, though fragrance pages serve identically almost everywhere, so geography is rarely the lever on this target. The 195+ geo-locations earn their keep spreading request origins for large backfills rather than changing what the pages contain.
A full designer-catalog backfill – every perfume, every note pyramid – is an overnight job at moderate concurrency. Steady-state afterwards is a trickle: new launches and vote refreshes. Plan tiers set the parallel ceiling, and scheduling handles the drip without attention.
Free to try in the literal sense – the starter plan activates with no card and includes up to 2K requests, which covers several designers' complete catalogs as a working sample.
Gain access to real-time data at any scale without worrying about proxy setup or blocks.
14-day money-back option