News Scraper API
Media monitoring breaks when every publisher uses a different layout. Our news scraper API standardizes scraping news articles – headline, byline, date, and body text arrive as fields, not markup.
* This scraper is now a part of the Web Data API.

125M+
IPs worldwide
99.99%
success rate
200
requests per second
100+
ready-made templates
Free
starter plan
Be ahead of the news scraping game
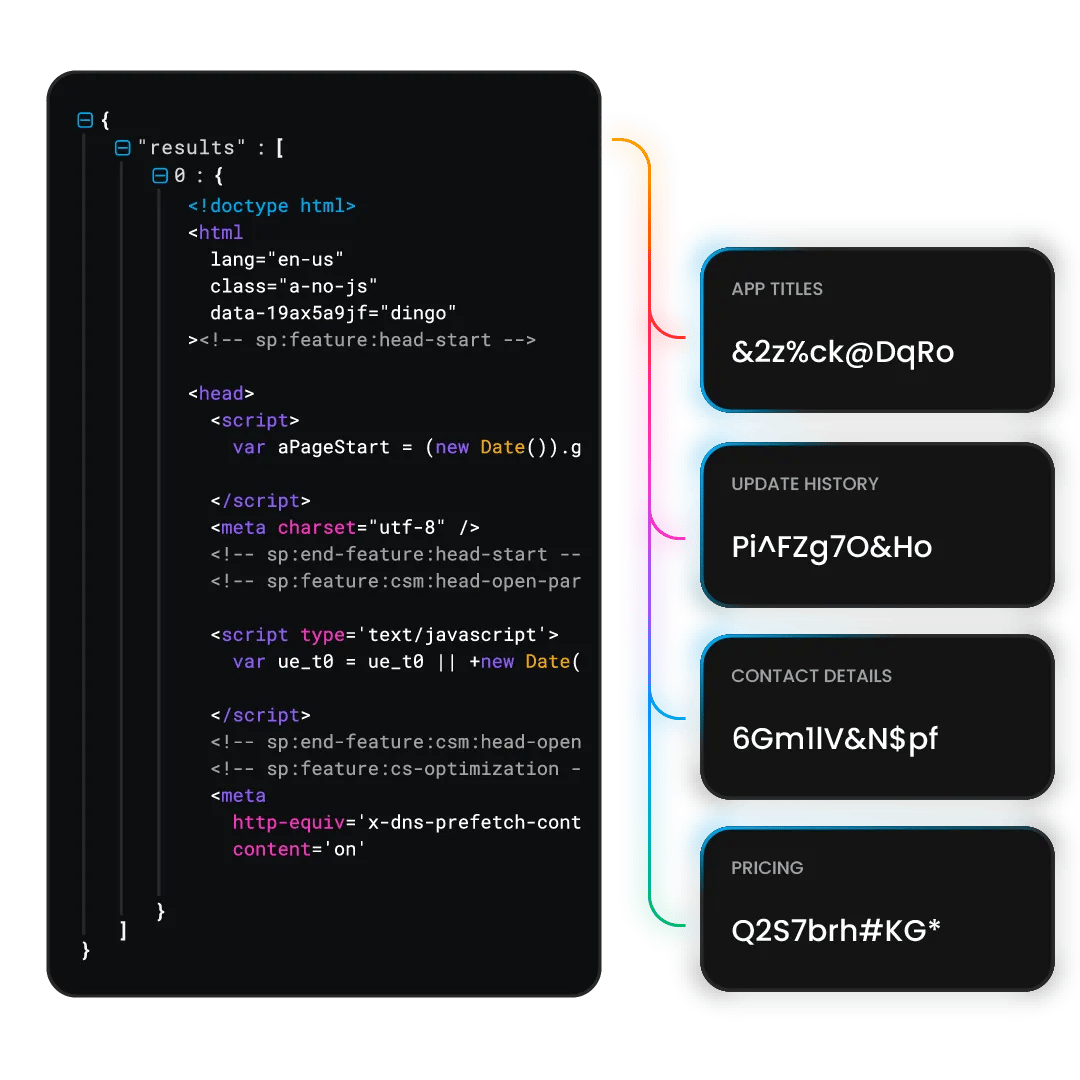
What is news scraper API?
What does a news scraper API return that an RSS feed does not? The article itself, read from the public page rather than a summary. Scraping news articles across a long publisher list means selector drift is the real maintenance cost, since every publisher runs its own template. Per article:
- Headline, subheading, and byline
- Publish and update timestamps
- Section, tags, and category
- Body text with paragraph structure
- Canonical URL and image captions
Body text is where the legal line sits, so most pipelines analyze it internally and publish only the headline, link, and timestamp.
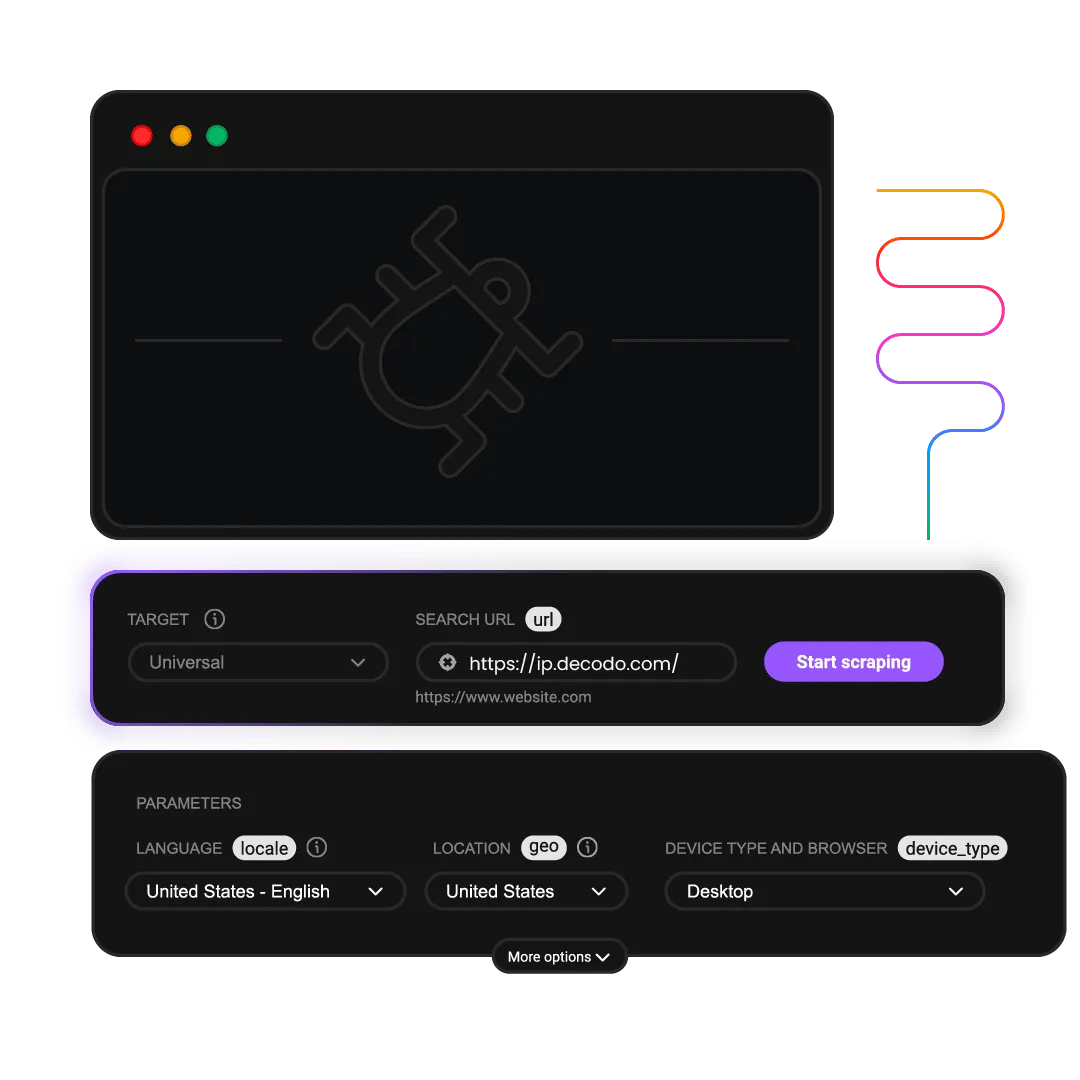
Collect news data
Filling a monitoring index or a training corpus takes volume, and the Web Data API supplies it from a single endpoint.
From request to storage:
1. Send one URL or a batch of article links
2. Render pages that load text through scripts
3. Route through 125M+ proxies spanning residential, mobile, ISP, and datacenter types
4. Take HTML or parsed JSON back
5. Pick from 195+ geo-locations for regional editions
6. Schedule recurring pulls per publisher

Built-in scraper
JavaScript rendering
Easy API integration
195+ geo-locations, including country-, state-, and city-level targeting
No CAPTCHAs or IP blocks
Scrape news with Python, Node.js, or cURL
Our news Scraper API works with every major programming language, so it plugs into the tools you already run.
Get more from the news scraper API
JavaScript rendering, proxy management, and CAPTCHA handling ship in one API call, so news data arrives without blocks.

100% success rate
Dead links and empty responses cost nothing. Charges apply per article that returns actual content.

Advanced anti-bot bypass
Publisher defenses run from none to strict. Request signatures, header rotation, and TLS handling cover the strict end.

Real-time or on-demand results
Poll a breaking story every few minutes, or queue an overnight pass across yesterday's archive.

125M+ proxy pool
Editions differ between countries. Choose residential, mobile, ISP, or datacenter routes among 195+ locations to capture the version local readers get.

JavaScript rendering
Many outlets load body copy and embeds after first paint. We wait for the render, then return the complete text.

Easy integration
Feed the endpoint a URL list and read results in Python, Node.js, or cURL. Sample scripts ship with the docs.
What does Web Data API cost?
Choose a plan based on your data collection volume. All plans include the same powerful features – you only pay for what you use. Start with the free plan to test before committing.
See full pricing details in the documentation.
With each plan, you access:

JavaScript rendering
99.99% success rate
HTML, Markdown, XHR, plus JSON, PNG where supported
One-click AI integrations
LLM-ready Markdown format
100+ pre-built templates
Single API key for all endpoints
/scrape, /search, /map, /crawl
24/7 tech support
14-day money-back
SSL Secure Payment
Your information is protected by 256-bit SSL

Why the scraping community chooses Decodo
135K+ developers, SEOs, and data teams rely on Decodo to collect public web data at scale – including from News. Whether you're shipping a side project or running production pipelines, our infrastructure is built to keep your News scraper running while you focus on what to do with the data.
Decodo
Manual data collection
Other APIs
125M+ residential, mobile, datacenter, and ISP proxies
Manage proxy rotation yourself
Limited proxy pools
Advanced browser fingerprinting
Build CAPTCHA solvers
Frequent CAPTCHA blocks
Only pay for successful requests
Handle retries manually
Pay for failed requests
100+ ready-made scraping templates
Maintenance overhead
Complex documentation
Data in JSON, CSV, HTML, and Markdown formats
Days to implement
Limited output formats
Why the scraping community chooses Decodo
135K+ developers, SEOs, and data teams rely on Decodo to collect public web data at scale – including from news. Side projects and production pipelines run on the same infrastructure, built to keep your news scraper up while you focus on the data itself.
Attentive service
The professional expertise of the Decodo solution has significantly boosted our business growth while enhancing overall efficiency and effectiveness.
N
Novabeyond
Easy to get things done
Decodo provides great service with a simple setup and friendly support team.
R
RoiDynamic
A key to our work
Decodo enables us to develop and test applications in varied environments while supporting precise data collection for research and audience profiling.
C
Cybereg

Trusted by:


Decodo blog
Build knowledge on our solutions and improve your workflows with step-by-step guides, expert tips, and developer articles.
Most recent
What Is T3 Code? Setup, Features and Use Cases
T3 Code is a free, open-source app for managing AI coding agents like Claude Code, Codex, and Cursor from a single desktop, web, or mobile interface. Developed by Theo Browne's T3 Tools team, it has become one of GitHub's fast-growing developer projects in 2026. In this guide, we'll cover what T3 Code does, its main features, how to get started, and how it compares to other coding tools.

Dominykas Niaura
Last updated: Nov 04, 2026
10 min read
Most popular
Residential vs. Datacenter Proxies: Which Should You Choose?
Residential and datacenter proxies both act as intermediaries that hide your real IP address, allowing you to access restricted websites and geo-blocked content. However, they differ in IP origin, stability, speed, and how websites perceive them. This residential vs. datacenter proxies guide breaks down their key differences.
Vilius Sakutis
Last updated: Sep 11, 2026
8 min read
Google Sheets Web Scraping: An Ultimate Guide for 2026
Google Sheets is a powerful data management tool, but few people know it can also pull data directly from the web without a single line of code. Using built-in import functions, you can scrape website content, parse tables, and pull live feeds straight into your spreadsheet. In this guide, you'll learn how to use IMPORTXML for XPath-based data extraction, IMPORTHTML for grabbing tables and lists, IMPORTFEED for RSS and Atom content, IMPORTDATA for CSV files, and IMPORTRANGE to link scraped data across spreadsheets. We'll also cover Google Apps Script for automation, common errors and how to fix them, and when to reach for a dedicated scraping tool instead.
Zilvinas Tamulis
Last updated: Mar 30, 2026
6 min read
Manage Your Business Reputation with SERP Scraping API
A widely available internet leaves the door open for people to find information about everything. For example, everyone can check a business's online presence before trusting it. So, everything that could be found online about your brand helps your potential audience evaluate if you’re legit.
Statistics only prove that – 9 out of 10 online shoppers admit that reviews influence their buying decisions. It stands to reason – checking unbiased opinions helps avoid low-value products and potential scams. And who wants that? So, for businesses analyzing their customers’ reviews becomes a not-to-miss-out factor.
However, reviews are just one part of the game. Brand reputation management consists of various elements that form the customers' perception of the company. If it’s still a gray area for you, this blog post could be your starting point.
Ella Moore
Last updated: Jun 20, 2022
7 min read
How to Scrape Google Without Getting Blocked
Nowadays, web scraping is essential for any business interested in gaining a competitive edge. It allows quick and efficient data extraction from a variety of sources and acts as an integral step toward advanced business and marketing strategies.
If done responsibly, web scraping rarely leads to any issues. But if you don’t follow data scraping best practices, you become more likely to get blocked. Thus, we’re here to share with you practical ways to avoid blocks while scraping Google.
James Keenan
Last updated: Feb 20, 2023
8 min read
What Is SERP Analysis and How To Do It in 2026?
SERP analysis means examining a search engine results page (SERP) for a keyword to understand what ranks, which features appear, and whether your content has a realistic chance of earning visibility and clicks. This guide walks through what SERP analysis is, the six steps to run one, and how to pull SERP data at scale.
Justinas Tamasevicius
Last updated: Oct 26, 2026
9 min read
What is an API?
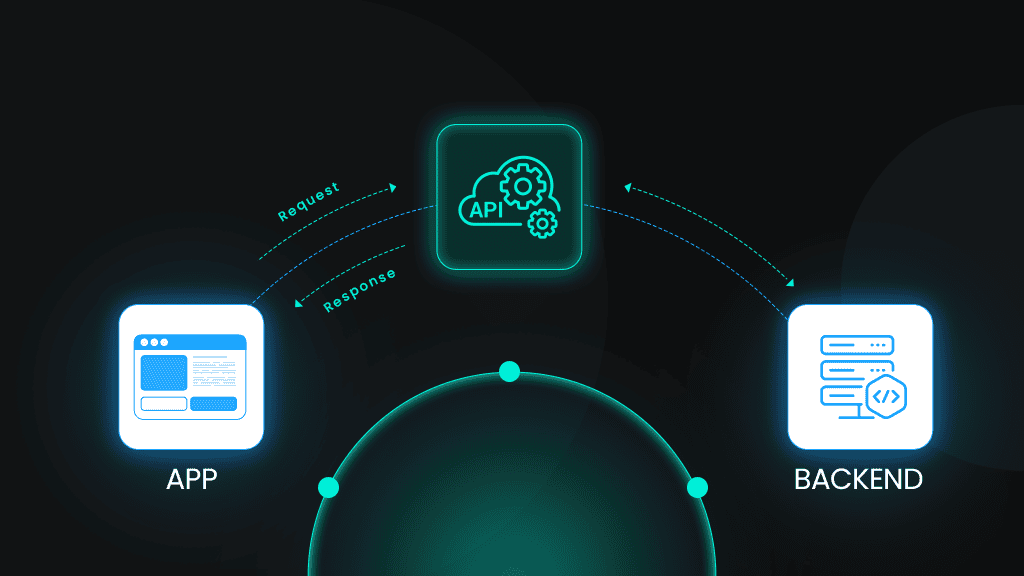
An application programming interface (API) works like a messenger. It allows different software systems to communicate without developers having to build custom links for every connection. For instance, one service might supply map data to a mobile app, while another handles payment processing for online transactions. In these times, that demands seamless integration, and APIs play a vital role. They automate tasks, enable large-scale data collection, and support sophisticated functions like web scraping and proxy management. By bridging diverse platforms and streamlining data exchange, they help businesses stay competitive and reduce the complexity of managing multiple, often inconsistent endpoints.
Kotryna Ragaišytė
Last updated: Mar 06, 2025
6 min read
How to Scrape Hotel Listings: Unlocking the Secrets
Scraping hotel listings is a powerful tool for gathering comprehensive data on accommodations, prices, and availability from various online sources. Whether you're looking to compare rates, analyze market trends, or create a personalized travel plan, scraping allows you to efficiently compile the information you need. In this article, we'll explain how to scrape hotel listings, ensuring you can leverage this data to its fullest potential.
Vilius Sakutis
Last updated: Nov 13, 2025
5 min read
What is Data Scraping? Definition and Best Techniques (2026)
The data scraping tools market is growing significantly, valued at approximately $875.46M in 2026. The market is projected to grow more due to the increasing demand for real-time data collection across various industries.
Vytautas Savickas
Last updated: Jan 30, 2026
6 min read

Web Crawling vs Web Scraping: What’s the Difference?
When it comes to gathering online data, two terms often create confusion: web crawling and web scraping. Although both involve extracting information from websites, they serve different purposes and employ distinct methods. In this article, we’ll break down these concepts, show you how they work, and help you decide which one suits your data extraction needs.
Justinas Tamasevicius
Last updated: Jul 01, 2025
7 min read
What Is Web Scraping? A Complete Guide to Its Uses and Best Practices
Web scraping is a powerful tool driving innovation across industries, and its full potential continues to unfold with each day. In this guide, we'll cover the fundamentals of web scraping – from basic concepts and techniques to practical applications and challenges. We’ll share best practices and explore emerging trends to help you stay ahead in this dynamic field.
Dominykas Niaura
Last updated: Jan 29, 2025
10 min read
Beautiful Soup Web Scraping: How to Parse Scraped HTML with Python
Web scraping with Python is a powerful technique for extracting valuable data from the web, enabling automation, analysis, and integration across various domains. Using libraries like Beautiful Soup and Requests, developers can efficiently parse HTML and XML documents, transforming unstructured web data into structured formats for further use. This guide explores essential tools and techniques to navigate the vast web and extract meaningful insights effortlessly.
Zilvinas Tamulis
Last updated: Mar 25, 2025
14 min read
Frequently asked questions
Is it legal to scrape news?
Headlines, metadata, and publish dates from public articles can normally be collected. Republishing full text is a different question, because article bodies are copyrighted. Most teams keep text for internal analysis, then surface short quotes with attribution. Check each publisher's Terms of Service, and treat author details as personal data.
How does the news scraper API bypass blocks and CAPTCHAs?
News sites span the whole defense spectrum. Every call picks an egress IP, applies a matching request signature, reorders headers, and negotiates TLS properly, with CAPTCHAs resolved in flight. For aggregator listings rather than article pages, reach for the Google News Scraper API.
What output formats does the news scraper API support?
Expect HTML first, and JSON where parsing covers the result format. CSV comes out of the dashboard. Large monitoring jobs tend to stream JSON into a search index. Our guide to scraping Google News results walks through one working pipeline.
Can I geo-target news requests to a specific country or city?
Yes. There are 195+ locations to target, with city-level and ZIP-level choices in parts of the network. Publishers often serve different editions, consent screens, or paywall prompts by country, and matching the origin keeps a corpus coherent.
How fast is the news scraper API and can it handle large-scale jobs?
Article volume is the constraint, not latency; concurrency follows the plan you pick. Responses land in seconds and thousands of URLs move together. Schedule per-publisher jobs, or trigger a pull when a feed updates.
Can I try the news scraper API for free?
Yes. News scraping falls inside the Web Data API starter plan, which opens without payment details. Point the quota at the publishers you actually monitor, since layout coverage varies between outlets far more than plan limits do.
News Scraper API for Your Data Needs
Gain access to real-time data at any scale without worrying about proxy setup or blocks.
14-day money-back option