Douyin Scraper API
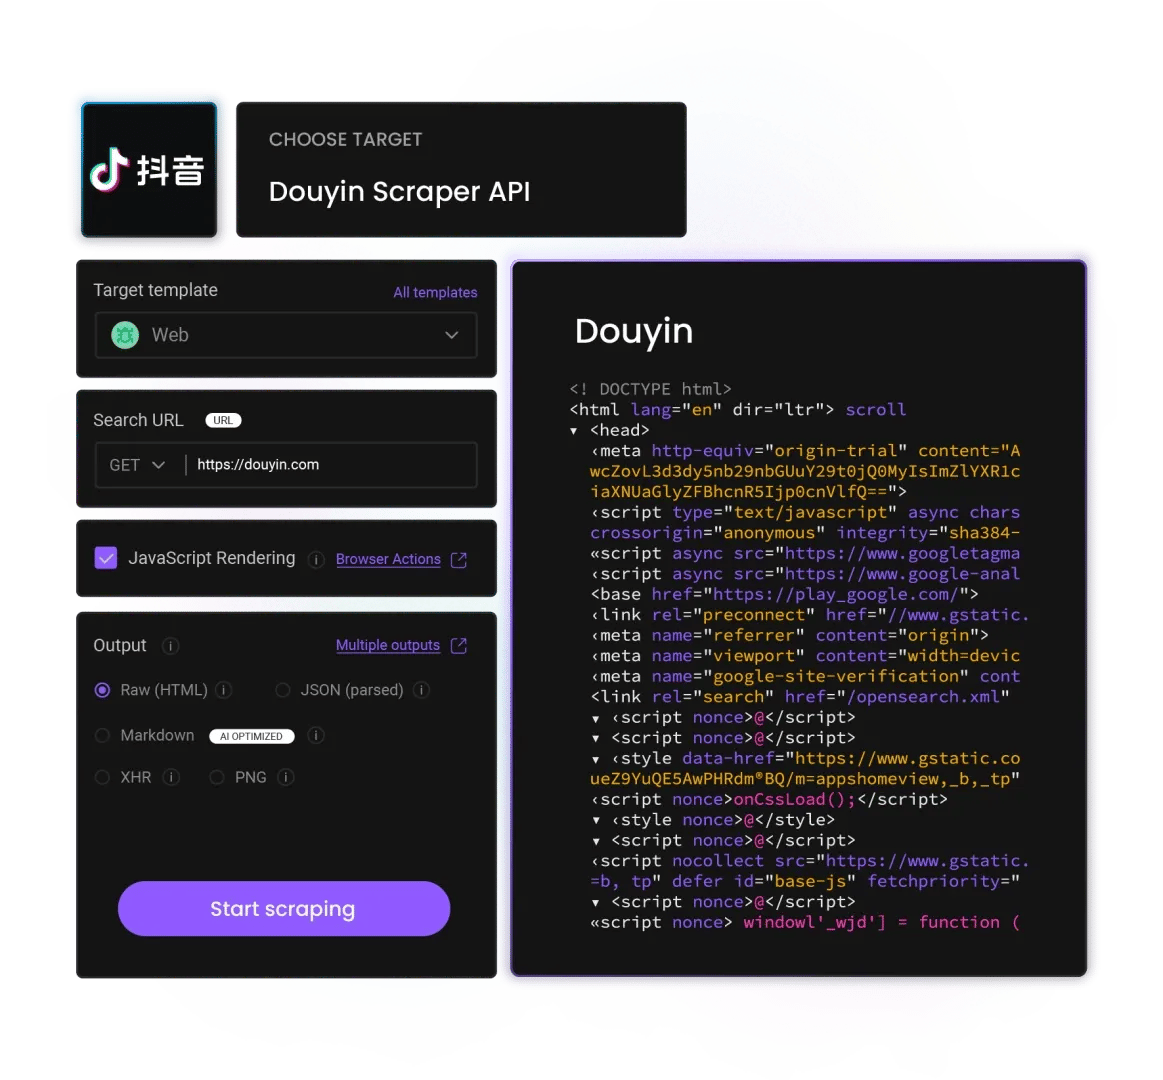
Chinese social trends are hard to watch from outside the country. A Douyin scraper API* reads public discover and profile pages from Chinese exits and returns video data as fields.
* This scraper is now a part of the Web Scraping API.
125M+
IPs worldwide
99.99%
success rate
200
requests per second
100+
ready-made templates
Free
starter plan
Be ahead of the Douyin scraping game
What is Douyin scraper API?
Anything behind an account is out of scope for a Douyin scraper API, the same boundary Decodo's Social Media Scraping API works within, and the public layer is where trend work happens anyway. It splits ę ways:
- The video – title, caption, hashtags, sound name, and posting time
- The numbers – view, like, comment, and share counts
- The placement – position in discover or search results for a term, plus creator handle and follower count
Sound name is the field Western analysts skip and Douyin analysts start with, because on this platform the audio travels before the video does.
Collect Douyin data
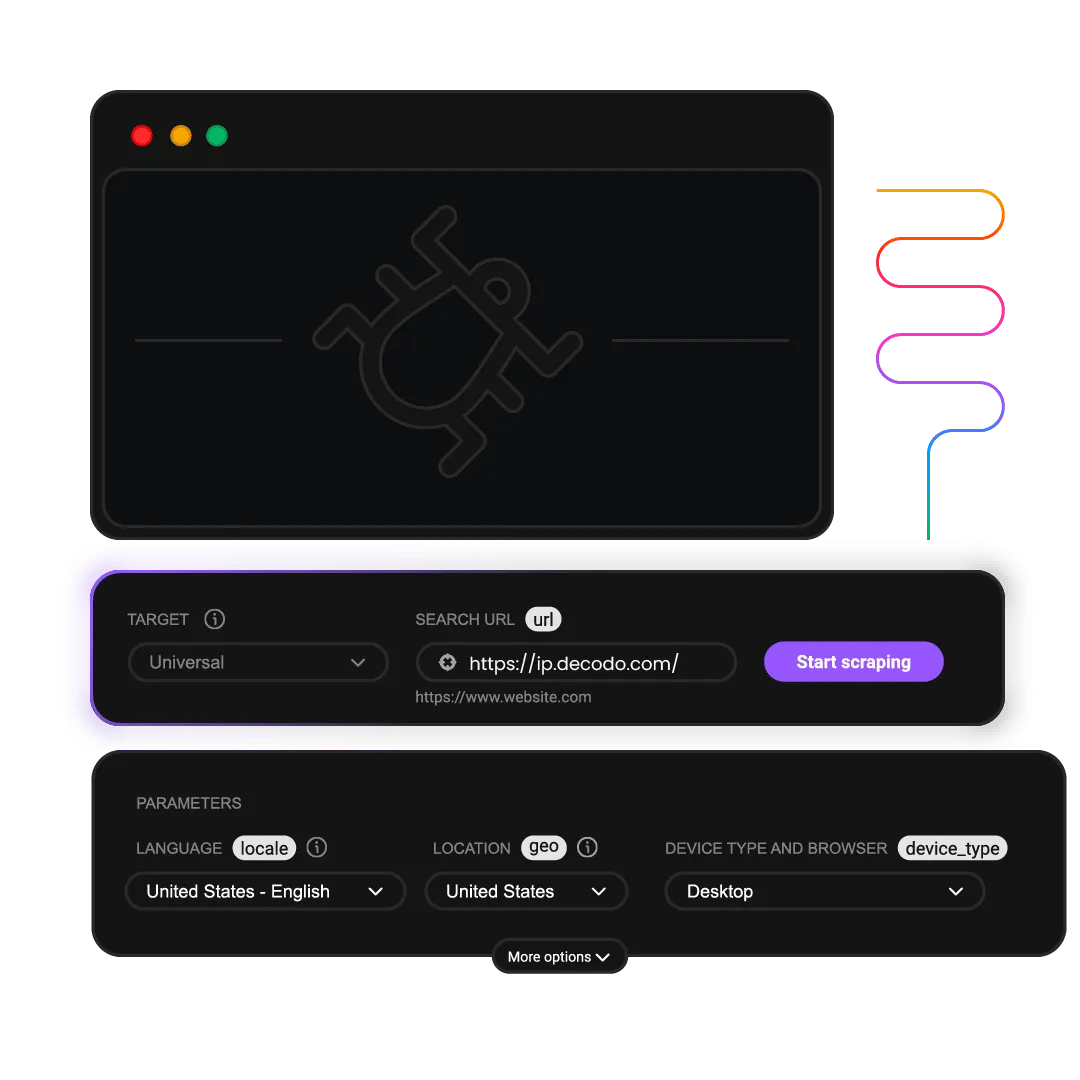
This platform serves Chinese traffic differently and defends itself accordingly, so the Web Scraping API makes exit country a decision you make per call.
Each one brings:
- Chinese exits among 195+ geo-locations
- 125M+ IPs in 4 proxy types
- Rendering for feeds that build while scrolling
- CAPTCHA handling and quiet repeats
- HTML, JSON, CSV, or Markdown output
- Charges only where a page returns

Built-in scraper
JavaScript rendering
Easy API integration
195+ geo-locations, including continent-, country-, state-, and city-, ZIP codo, and ASN-level targeting
No CAPTCHAs or IP blocks
Scrape Douyin with Python, Node.js, or cURL
Our Douyin Scraper API works with every major programming language, so it plugs into the tools you already run.
Get more from the Douyin scraper API
JavaScript rendering, proxy management, and CAPTCHA handling ship in one API call, so Douyin data arrives without blocks.

100% success rate
Requests the platform turns away aren't billed. Videos that return with metrics are the chargeable part.

Advanced anti-bot bypass
Defenses here are among the most active anywhere, and they read cadence as much as origin. Fresh exits with matching fingerprints per request are what keep a trend sweep running.

Real-time or on-demand results
Track a hashtag through a campaign week, or pull 1 creator's recent posts before a briefing.

125M+ proxy pool
Feeds differ sharply between a request inside China and a request from outside. Choose the origin among 195+ locations, then route over residential, mobile, ISP, or datacenter proxies.

JavaScript rendering
Feeds assemble as they scroll, so a plain fetch returns almost nothing usable. Executing the page fully returns loaded video cards.

Easy integration
Try it in cURL, run it in Python or Node.js, and hand the daily hashtag list to n8n.
What does Web Scraping API cost?
Choose a plan based on your scraping volume. All plans include the same powerful features – you only pay for what you use. Start with the free plan to test before committing.
Plan prices
+VAT / Billed monthly
Rate limit
All prices shown are per 1K req.
Plan price
$0
+VAT / Billed monthly
Request type
Price per 1k req.
2K req.
$0.50
1K req.
$0.75
1K req.
$1.00
667 req.
$1.50
Rate limit
10 req/s
Plan price
$19
+VAT / Billed monthly
Request type
Price per 1k req.
38K req.
$0.50
25K req.
$0.75
19K req.
$1.00
12K req.
$1.50
Rate limit
10 req/s
Plan price
$49
+VAT / Billed monthly
Request type
Price per 1k req.
163K req.
$0.30
75K req.
$0.65
54K req.
$0.90
39K req.
$1.25
Rate limit
25 req/s
Plan price
$99
+VAT / Billed monthly
Request type
Price per 1k req.
707K req.
$0.14
165K req.
$0.60
116K req.
$0.85
82K req.
$1.20
Rate limit
50 req/s
Need more?
Request type
Price per 1k req.
Custom
Custom
Custom
Custom
Rate limit
Custom
For low-security sites and simple access
For accessing guarded or sensitive pages
With each plan, you access:
99.99% success rate
Results in HTML, JSON, CSV, XHR or PNG
MCP server
JavaScript rendering
AI integrations
100+ pre-built templates
Supports search, pagination, and filtering
LLM-ready markdown format
24/7 tech support
14-day money-back
SSL Secure Payment
Your information is protected by 256-bit SSL

Why the scraping community chooses Decodo
135K+ developers, SEOs, and data teams rely on Decodo to collect public web data at scale – including from Douyin. Whether you're shipping a side project or running production pipelines, our infrastructure is built to keep your Douyin scraper running while you focus on what to do with the data.
Decodo
Manual data collection
Other APIs
125M+ residential, mobile, datacenter, and ISP proxies
Manage proxy rotation yourself
Limited proxy pools
Advanced browser fingerprinting
Build CAPTCHA solvers
Frequent CAPTCHA blocks
Only pay for successful requests
Handle retries manually
Pay for failed requests
100+ ready-made scraping templates
Maintenance overhead
Complex documentation
Data in JSON, CSV, HTML, and Markdown formats
Days to implement
Limited output formats
Why the scraping community chooses Decodo
135K+ developers, SEO specialists, and data teams rely on Decodo to collect public web data at scale – including from Douyin. Side projects and production pipelines run on the same infrastructure, built to keep your Douyin scraper API up while you focus on the data itself.
Attentive service
The professional expertise of the Decodo solution has significantly boosted our business growth while enhancing overall efficiency and effectiveness.
N
Novabeyond
Easy to get things done
Decodo provides great service with a simple setup and friendly support team.
R
RoiDynamic
A key to our work
Decodo enables us to develop and test applications in varied environments while supporting precise data collection for research and audience profiling.
C
Cybereg

Trusted by:


Decodo blog
Build knowledge on our solutions and improve your workflows with step-by-step guides, expert tips, and developer articles.
Most recent
AI Firms Are Destroying Rare Books for Training Data: Scraping Is the Alternative
Book scraping is the process of collecting public book data, such as titles, ratings, reviews, metadata, and available text, from online sources. It has taken on new relevance as AI companies buy and destructively scan physical books for training data. For material that already exists online, scraping offers a lower-friction, non-destructive way to collect some of the same kind of human-written data.

Justinas Tamasevicius
Last updated: Sep 14, 2026
8 min read
Most popular
Residential vs. Datacenter Proxies: Which Should You Choose?
Residential and datacenter proxies both act as intermediaries that hide your real IP address, allowing you to access restricted websites and geo-blocked content. However, they differ in IP origin, stability, speed, and how websites perceive them. This residential vs. datacenter proxies guide breaks down their key differences.
Vilius Sakutis
Last updated: Sep 11, 2026
8 min read
Google Sheets Web Scraping: An Ultimate Guide for 2026
Google Sheets is a powerful data management tool, but few people know it can also pull data directly from the web without a single line of code. Using built-in import functions, you can scrape website content, parse tables, and pull live feeds straight into your spreadsheet. In this guide, you'll learn how to use IMPORTXML for XPath-based data extraction, IMPORTHTML for grabbing tables and lists, IMPORTFEED for RSS and Atom content, IMPORTDATA for CSV files, and IMPORTRANGE to link scraped data across spreadsheets. We'll also cover Google Apps Script for automation, common errors and how to fix them, and when to reach for a dedicated scraping tool instead.
Zilvinas Tamulis
Last updated: Mar 30, 2026
6 min read
Manage Your Business Reputation with SERP Scraping API
A widely available internet leaves the door open for people to find information about everything. For example, everyone can check a business's online presence before trusting it. So, everything that could be found online about your brand helps your potential audience evaluate if you’re legit.
Statistics only prove that – 9 out of 10 online shoppers admit that reviews influence their buying decisions. It stands to reason – checking unbiased opinions helps avoid low-value products and potential scams. And who wants that? So, for businesses analyzing their customers’ reviews becomes a not-to-miss-out factor.
However, reviews are just one part of the game. Brand reputation management consists of various elements that form the customers' perception of the company. If it’s still a gray area for you, this blog post could be your starting point.
Ella Moore
Last updated: Jun 20, 2022
7 min read
How to Scrape Google Without Getting Blocked
Nowadays, web scraping is essential for any business interested in gaining a competitive edge. It allows quick and efficient data extraction from a variety of sources and acts as an integral step toward advanced business and marketing strategies.
If done responsibly, web scraping rarely leads to any issues. But if you don’t follow data scraping best practices, you become more likely to get blocked. Thus, we’re here to share with you practical ways to avoid blocks while scraping Google.
James Keenan
Last updated: Feb 20, 2023
8 min read
What Is SERP Analysis And How To Do It?
SERP (Search Engine Results Page) analysis involves examining search engine results for specific keywords to understand website rankings. It helps identify the content, format, and optimization strategies used by top-ranking pages and uncovers opportunities for improving rankings. In this blog post, we’re exploring what SERP analysis is, how to conduct it, and how it can help you.
James Keenan
Last updated: Feb 20, 2023
7 min read
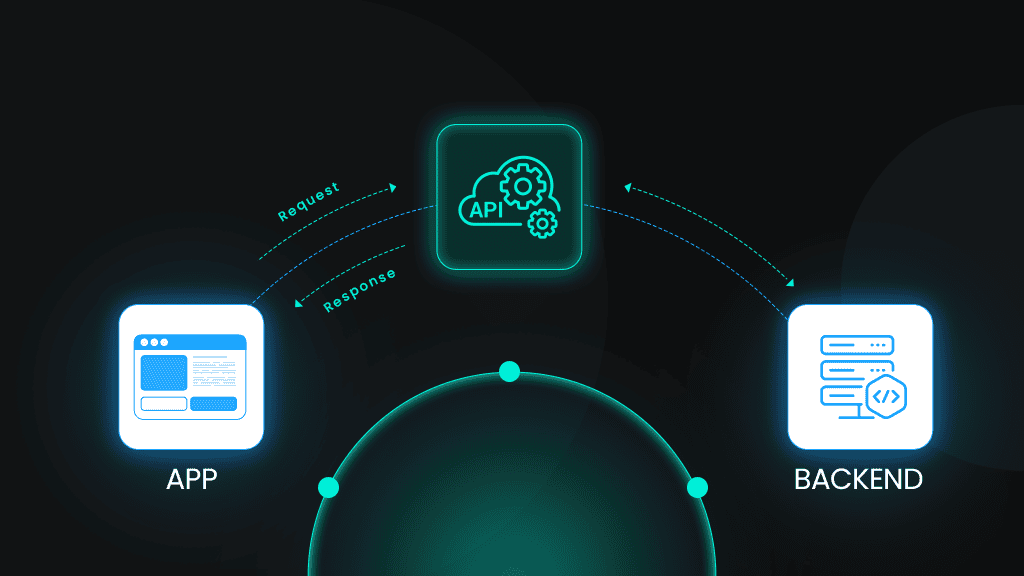
What is an API?
An application programming interface (API) works like a messenger. It allows different software systems to communicate without developers having to build custom links for every connection. For instance, one service might supply map data to a mobile app, while another handles payment processing for online transactions. In these times, that demands seamless integration, and APIs play a vital role. They automate tasks, enable large-scale data collection, and support sophisticated functions like web scraping and proxy management. By bridging diverse platforms and streamlining data exchange, they help businesses stay competitive and reduce the complexity of managing multiple, often inconsistent endpoints.
Kotryna Ragaišytė
Last updated: Mar 06, 2025
6 min read
How to Scrape Hotel Listings: Unlocking the Secrets
Scraping hotel listings is a powerful tool for gathering comprehensive data on accommodations, prices, and availability from various online sources. Whether you're looking to compare rates, analyze market trends, or create a personalized travel plan, scraping allows you to efficiently compile the information you need. In this article, we'll explain how to scrape hotel listings, ensuring you can leverage this data to its fullest potential.
Vilius Sakutis
Last updated: Nov 13, 2025
5 min read
What is Data Scraping? Definition and Best Techniques (2026)
The data scraping tools market is growing significantly, valued at approximately $875.46M in 2026. The market is projected to grow more due to the increasing demand for real-time data collection across various industries.
Vytautas Savickas
Last updated: Jan 30, 2026
6 min read

Web Crawling vs Web Scraping: What’s the Difference?
When it comes to gathering online data, two terms often create confusion: web crawling and web scraping. Although both involve extracting information from websites, they serve different purposes and employ distinct methods. In this article, we’ll break down these concepts, show you how they work, and help you decide which one suits your data extraction needs.
Justinas Tamasevicius
Last updated: Jul 01, 2025
7 min read
What Is Web Scraping? A Complete Guide to Its Uses and Best Practices
Web scraping is a powerful tool driving innovation across industries, and its full potential continues to unfold with each day. In this guide, we'll cover the fundamentals of web scraping – from basic concepts and techniques to practical applications and challenges. We’ll share best practices and explore emerging trends to help you stay ahead in this dynamic field.
Dominykas Niaura
Last updated: Jan 29, 2025
10 min read
Beautiful Soup Web Scraping: How to Parse Scraped HTML with Python
Web scraping with Python is a powerful technique for extracting valuable data from the web, enabling automation, analysis, and integration across various domains. Using libraries like Beautiful Soup and Requests, developers can efficiently parse HTML and XML documents, transforming unstructured web data into structured formats for further use. This guide explores essential tools and techniques to navigate the vast web and extract meaningful insights effortlessly.
Zilvinas Tamulis
Last updated: Mar 25, 2025
14 min read
Frequently asked questions
Is it legal to scrape Douyin?
Moving data between countries can add its own requirements. Where records are stored and who can reach them may matter as much as how they were collected. Douyin is no different from any other international source. Map the flow before you build it. Read our cross-border data guide first.
How does the Douyin scraper API bypass blocks and CAPTCHAs?
Exit and fingerprint turn over on each call, and challenges are resolved ahead of the response. A refused call repeats free. Decodo's Site Unblocker applies the same treatment to other guarded platforms.
What output formats does the Douyin scraper API support?
HTML unless JSON is asked for, which parsed feeds support, plus CSV for a trend deck. Campaign tracking keeps JSON, since view counts only show momentum with timestamps attached.
Can I geo-target Douyin requests to a specific country or city?
Yes, and here it decides whether you see anything worth having. Origin spans 195+ locations, and Chinese exits are what return the domestic feed rather than a thin outside view.
How fast is the Douyin scraper API and can it handle large-scale jobs?
Hashtags and creators run together up to your plan's limit, which is enough for a daily trend panel. Each response arrives in seconds.
Can I try the Douyin scraper API for free?
Yes. No card is required for the free Web Scraping API starter plan, which holds up to 2K requests. Check that the fields you need appear in a response before planning any volume. Platform restrictions and personal data both apply here, so confirm your scope first.
Douyin Scraper API for Your Data Needs
Gain access to real-time data at any scale without worrying about proxy setup or blocks.
14-day money-back option